


Summary:
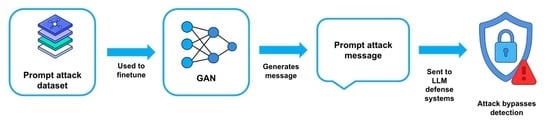
Generative Adversarial Networks (GANs) using Long Short-Term Memory (LSTM) provide a computationally cheaper approach for text generation compared to large language models (LLMs). The low hardware barrier of training GANs poses a threat because it means more bad actors may use them to mass-produce prompt attack messages against LLM systems. Thus, to better understand the threat of GANs being used for prompt attack generation, we train two well-known GAN architectures, SeqGAN and RelGAN, on prompt attack messages. For each architecture, we evaluate generated prompt attack messages, comparing results with each other, with generated attacks from another computationally cheap approach, a 1-billion-parameter Llama 3.2 small language model (SLM), and with messages from the original dataset. This evaluation suggests that GAN architectures like SeqGAN and RelGAN have the potential to be used in conjunction with SLMs to readily generate malicious prompts that impose new threats against LLM-based systems such as chatbots. Analyzing the effectiveness of state-of-the-art defenses against prompt attacks, we also find that GAN-generated attacks can deceive most of these defenses with varying levels of success with the exception of Meta’s PromptGuard. Further, we suggest an improvement of prompt attack defenses based on the analysis of the language quality of the prompts, which we found to be the weakest point of GAN-generated messages.
Spanish layman's summary:
Este artículo muestra que modelos GANs sencillos como SeqGAN y RelGAN puede generar prompts maliciosos contra LLMs, como chatbots. Los bajos requisitos de hardware permite a actores maliciosos la producción masiva de ataques. Las defensas de LLS deben ser mejoradas para bloquear estos ataques.
English layman's summary:
This paper shows how lightweight GANs like SeqGAN and RelGAN can craft malicious prompts against LLMs, especially chatbots. Their low hardware needs enable mass production of such attacks by malicious actors. LLM defenses should be improved to block these type of attacks.
Keywords: AI Cybersecurity; adversarial prompts; large language models; Generative Adversarial Network
JCR-JIF Impact Factor and WoS quartile: 6,000 - Q1 (2024)
DOI reference:
 https://doi.org/10.3390/make7030077
Published on paper: September 2025.
Published on-line: August 2025.
Citation:
S. Rashid, E. Bollis, L. Pellicer, D. Rabbani, R. Palacios, A. Gupta, A. Gupta, "Evaluating Prompt Injection Attacks with LSTM-Based Generative Adversarial Networks: A Lightweight Alternative to Large Language Models", Machine Learning and Knowledge Extraction, Vol. 7, nº. 3, pp. 77, September 2025. [Online: August 2025] doi: 10.3390/make7030077


 Download this paper